pline.ai

/crawl

Follow links across a whole site

Point pline.ai at a website and get the text from every page back, clean and ready to use. You set how deep it goes and how many pages.

POST/crawl
curl -X POST "https://apix.pline.ai/v1/crawl" \
  -H "Content-Type: application/json" \
  -H "x-api-key: YOUR_API_KEY" \
  -d '{"url": "https://example.com", "limit": 500, "output": ["markdown"]}'

Crawl at scale

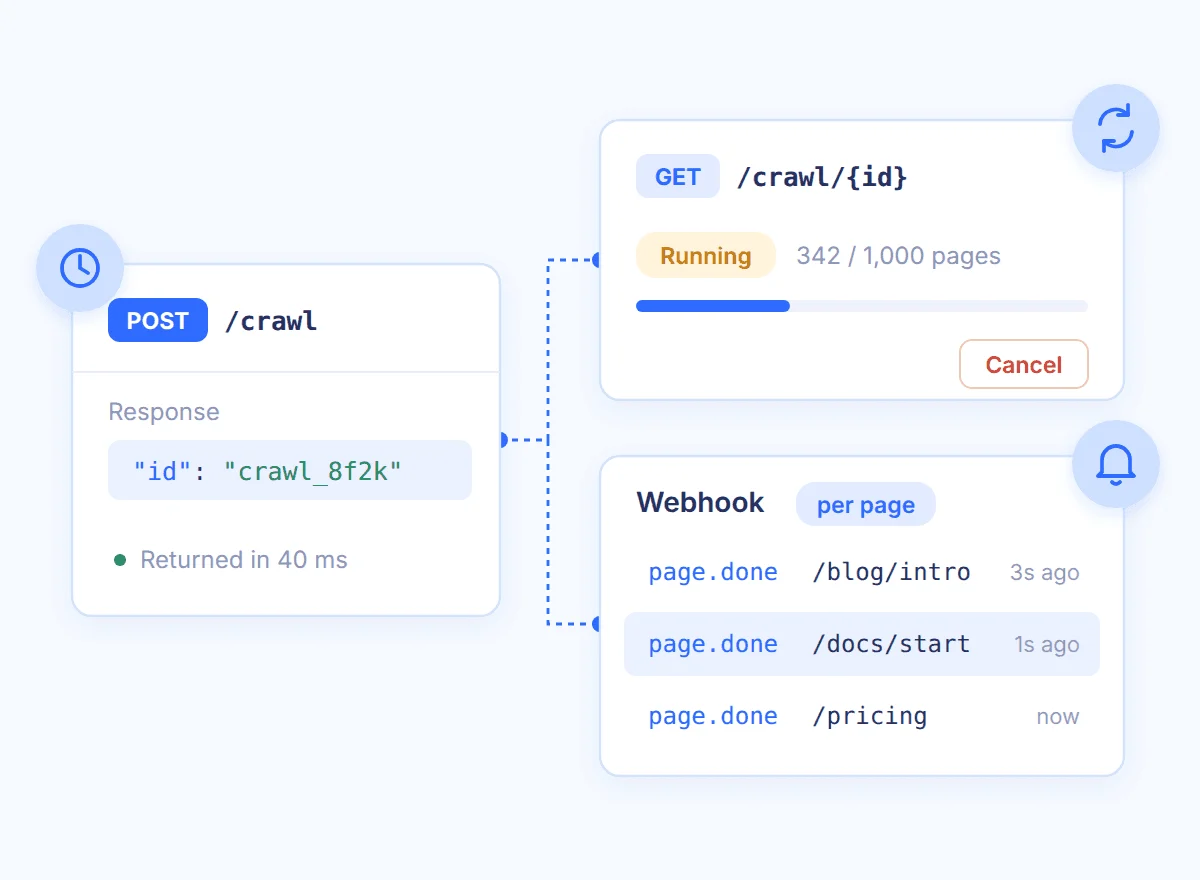
Async by design, delivered your way

Long crawls run in the background. Start a job, get an ID straight away, and pick up results as pages finish.

  • Check progress any time with the job ID
  • Get a webhook the second each page finishes
  • Cancel a running crawl mid-flight
Async by design, delivered your way

You're in control

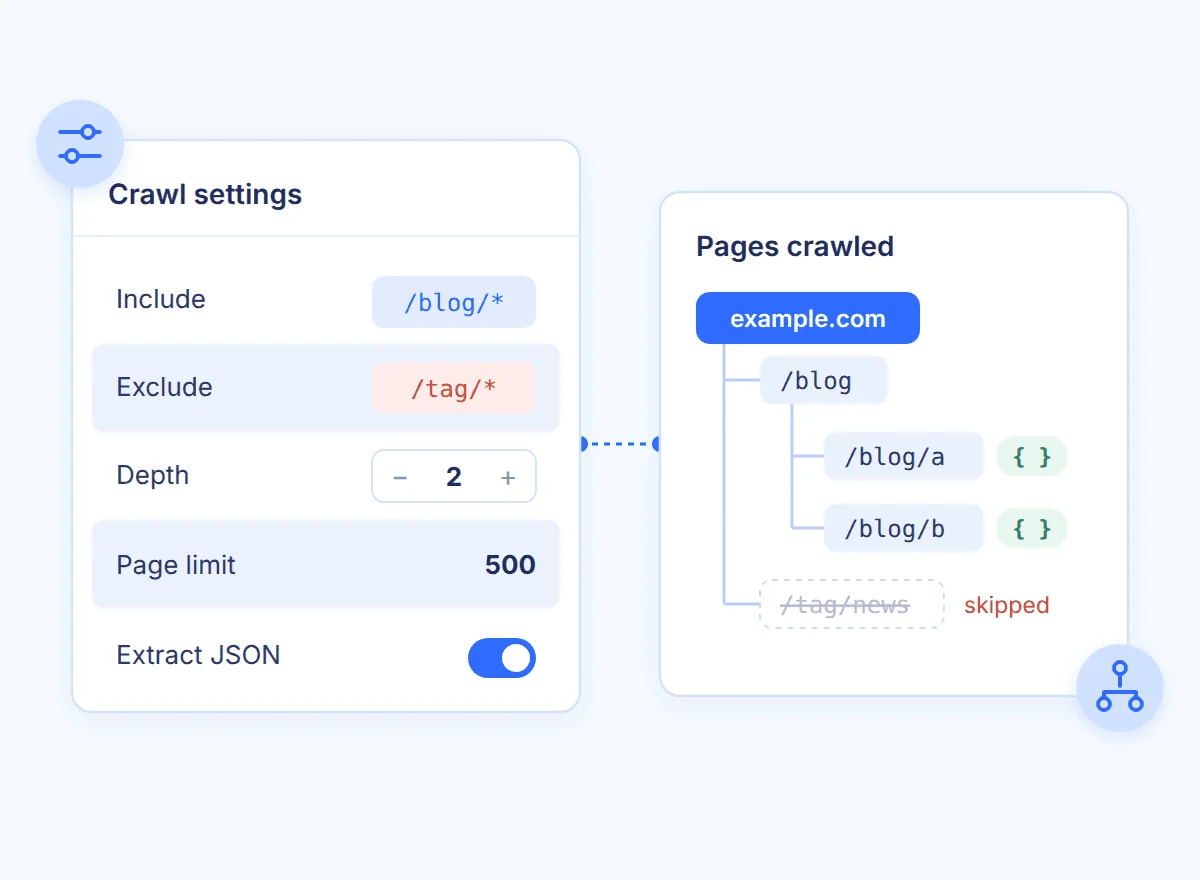
Crawl only what you need

Choose which paths to include or skip, how deep to go and how many pages to crawl. Every page can use the same /scrape settings, including JSON extraction.

  • Include or skip paths with patterns
  • Set depth and page limits
  • Extract JSON from every page
Crawl only what you need

Nothing gets lost

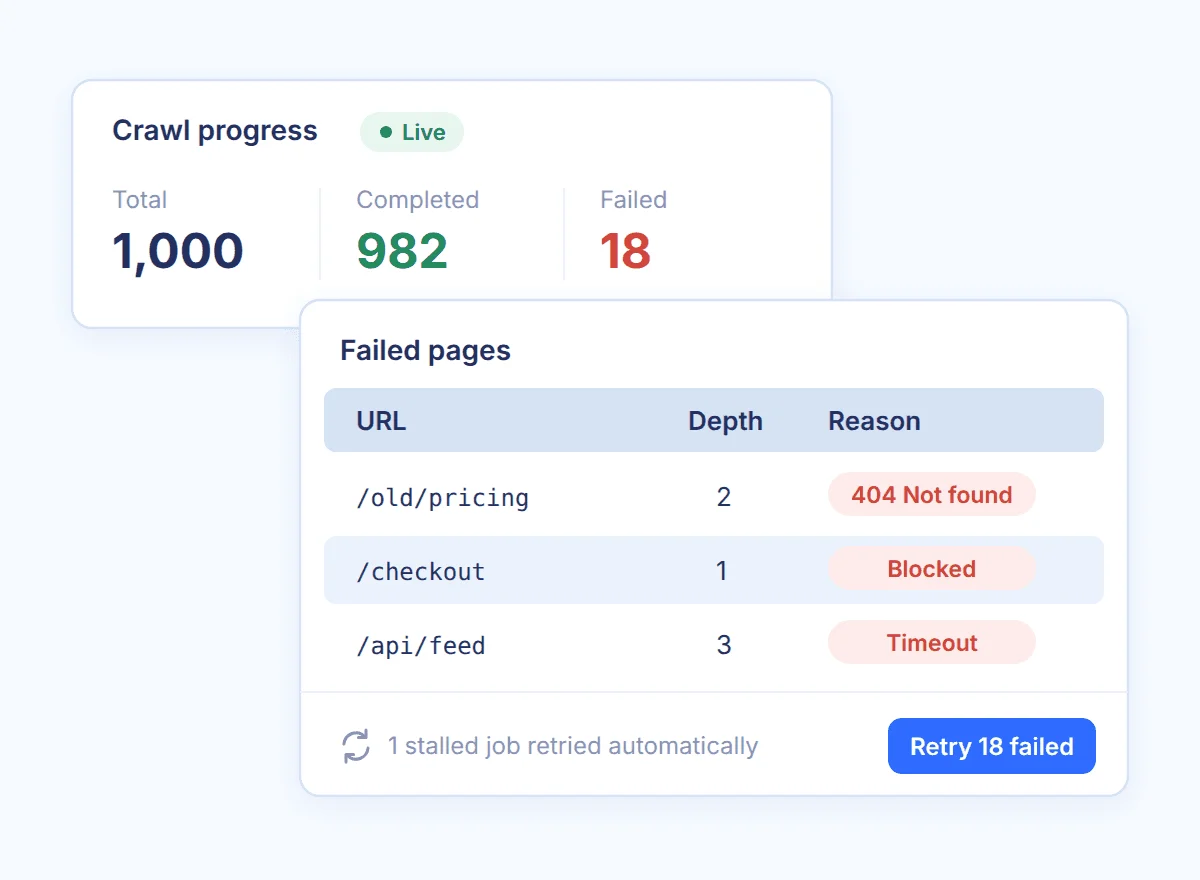
Failed pages don't stop the crawl

If a page fails, the crawl keeps going. You get a count of failed pages and a list with each URL and the reason, so you can retry only those.

  • Live counts: total, completed, failed
  • Each error lists URL, depth and reason
  • Stalled jobs are retried automatically
Failed pages don't stop the crawl

Use cases

What teams build with /crawl

Turn docs into a knowledge base

Crawl a docs site into clean Markdown and load it into your AI assistant or search.

Collect data across a whole section

Pull structured JSON from every product, listing or article page in one job.

Keep a copy of a site

Save full sections of a site on a schedule to track what changed.

Works with

One API key. Four endpoints.

FAQs

Get answers to the most asked questions

Ready to power your AI products with clean, real-time data?